MCP vs. REST APIs for Agentic Tools: When Each Actually Wins
A practical breakdown of when Model Context Protocol beats a traditional REST API for agentic AI tools, and when REST is still the better call.
The short answer
Keep stable, high-traffic operations that more than just an agent consumes on REST, and use MCP at the tool-calling boundary where the model discovers actions at runtime through list_tools. Most production agentic systems end up using both, and an existing REST API gains agentic calling through a thin MCP server that wraps its endpoints instead of a rewrite.
If you’re building anything agentic right now, you’ve almost certainly hit this decision point: wire up a REST API the model can call, or expose an MCP server instead. Most explanations of the difference stay abstract — “MCP is for tools, REST is for services” — which doesn’t actually help you decide anything. Here’s the version that does.
What actually changes structurally
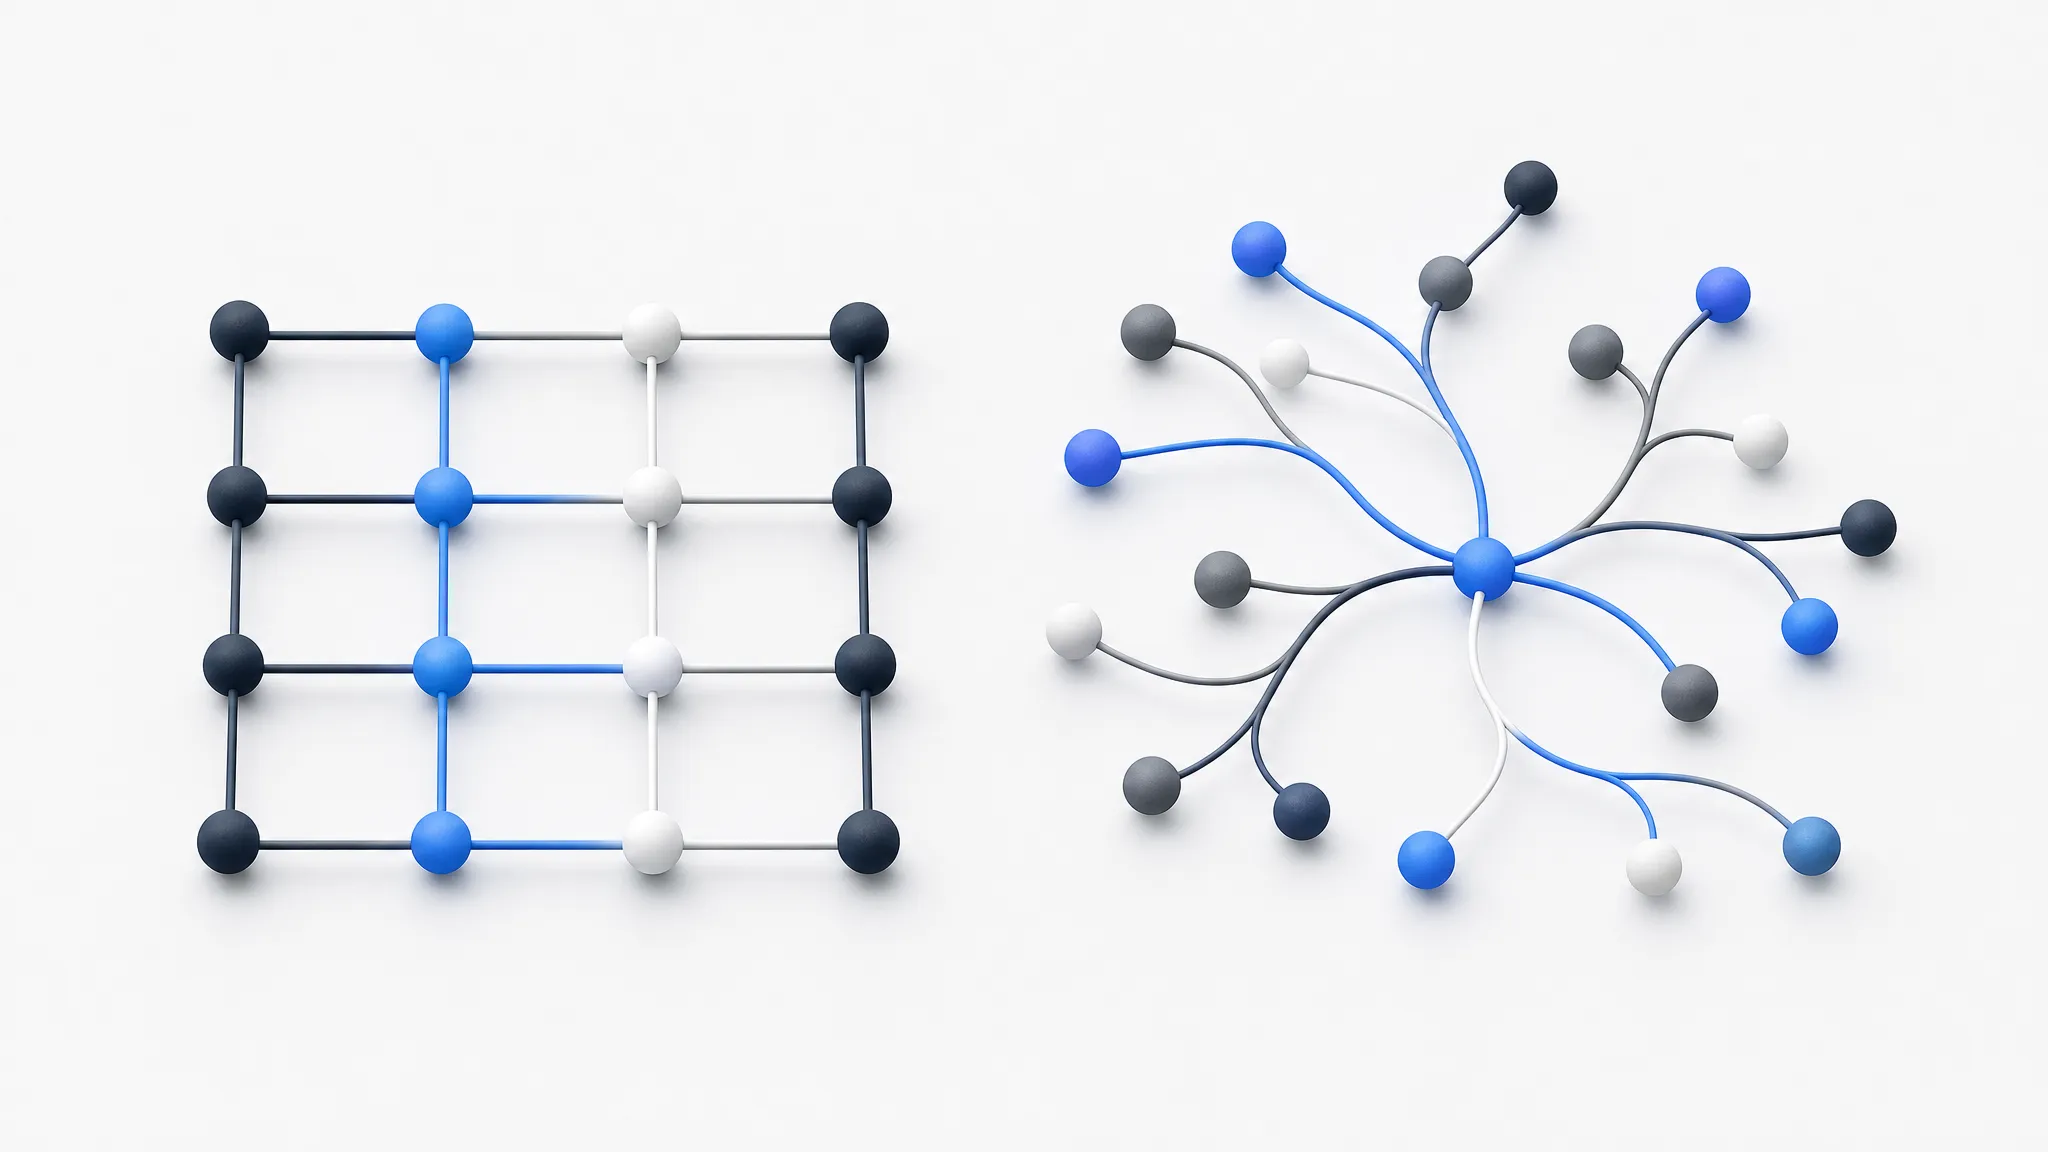
A REST API is built around fixed, pre-known endpoints. The client — in this case, an LLM-driven agent — needs to already know the shape of the request and response, usually via a spec like OpenAPI that gets translated into a tool definition ahead of time. Every new capability means writing a new endpoint and updating that spec.
MCP flips that. A server exposes a list_tools call that tells the model, at runtime, exactly what it can do and what parameters each action needs. The model doesn’t need the capability baked in ahead of time — it discovers it live, in a schema shaped specifically for LLM consumption rather than adapted from a human-facing API. That’s the actual structural difference: static, pre-declared capability vs. dynamic, discoverable capability.
MCP also supports persistent, stateful sessions over its transport (stdio or SSE), where REST is fundamentally stateless by design — each request stands alone, with any session state handled manually by the client or via tokens/cookies layered on top.
Where REST still wins
REST isn’t obsolete just because MCP exists for agentic use cases, and it’s worth being direct about where it’s still the better choice:
- Maturity and tooling. Two decades of auth standards (OAuth, API keys), caching layers, rate-limiting infrastructure, monitoring, and documentation conventions exist for REST. MCP’s ecosystem is a fraction of that age.
- Non-agentic consumers. If your API is called by web frontends, mobile apps, and other services — not just an LLM — REST (or GraphQL) remains the sensible shared interface. Building MCP-only would mean maintaining a second interface anyway.
- Simplicity for a small, fixed set of operations. If you have three endpoints that never change, the dynamic-discovery overhead of MCP buys you nothing. A static OpenAPI spec is simpler to reason about, test, and secure for a fixed surface.
- Wider hosting and infra support. Every cloud provider, every framework, every load balancer understands REST out of the box. MCP hosting patterns are still stabilizing.
Where MCP wins
- Tool discovery at runtime. If you’re building something where the available actions genuinely change — plugins, user-installed extensions, an evolving toolset — MCP’s live discovery avoids the constant spec-and-redeploy cycle REST would require.
- LLM-native schemas. MCP tool definitions are designed to be read directly by a model, cutting out the translation layer most REST-to-LLM integrations need (a wrapper that turns OpenAPI into a function-calling schema, essentially reinventing part of what MCP already standardizes).
- Composability across tools from different sources. An agent connecting to several MCP servers gets a single consistent interaction pattern regardless of who built each server. Doing the same across a handful of independently-designed REST APIs means handling several different auth schemes, error formats, and pagination styles.
- Session-aware interactions. Multi-step, stateful tool use (a server that remembers context across several calls in one session) is native to MCP’s design, where REST needs custom session-management code layered on top.
A concrete example: building a support-ticket agent
Abstract trade-offs are easier to weigh against a real scenario. Say you’re building an agent that helps triage support tickets — it needs to read ticket details, search a knowledge base, and occasionally create a follow-up task in a project tool.
- Reading ticket details and searching the knowledge base — these are typically stable, well-defined operations your whole team (not just the agent) already relies on. Keep these on REST. You likely already have these endpoints, they’re probably already documented, and other parts of your product probably already call them.
- Creating a follow-up task — if this means calling into a third-party project tool (Linear, Jira, Asana) that your agent needs to interact with flexibly, and where the available actions might expand over time (add a comment, change priority, assign a user), this is a much better fit for MCP. You get dynamic discovery of whatever that tool exposes, without hand-writing and maintaining a wrapper for every action you might eventually need.
- The agent’s own reasoning loop — this is where MCP’s session-awareness genuinely helps, since the agent may need to reference something it looked up two tool calls ago without your code manually threading that state through.
Notice what didn’t happen here: nothing got fully migrated from REST to MCP, and nothing got built MCP-only from scratch. The stable, shared-infrastructure parts stayed REST. The agent-specific, evolving, tool-calling surface became MCP. That’s the pattern worth defaulting to rather than picking one architecture for the whole system.
Migrating incrementally, if you’re starting from an existing REST API
If you already have a REST API and want to add agentic tool-calling without a rewrite, the practical path is usually a thin MCP server that wraps your existing REST endpoints — translating MCP’s list_tools/call_tool pattern into calls against the API you already have. This gets you MCP’s discovery and LLM-native schema benefits at the agent boundary, without duplicating your actual business logic or auth layer. It’s not free — you’re maintaining a translation layer — but it’s considerably less work than rebuilding core services as MCP servers from scratch, and it keeps your non-agentic consumers (web app, mobile app) unaffected.
The biggest mistake teams make right now is treating this as an all-or-nothing choice. In practice, most production agentic systems end up using both: REST for the stable, high-traffic, non-agentic parts of the system, and MCP specifically for the tool-calling surface the agent interacts with.
Other things worth knowing before you commit:
- MCP’s security model is younger and less battle-tested. We covered this in more depth in our piece on auditing MCP servers for supply-chain risk — the short version is that MCP’s permission and vetting ecosystem hasn’t caught up to how much access a typical server gets granted. REST’s auth patterns, by comparison, are extremely well understood.
- Not every MCP server implementation is equally solid. Since the spec is young, quality and security posture varies a lot between server implementations. Vet an MCP server the way you’d vet any new dependency, not the way you’d trust an established REST API.
- Latency characteristics differ by transport. stdio-based MCP servers running locally can be faster than a network REST call, but SSE-based remote MCP servers introduce their own latency profile that’s worth benchmarking for your specific setup rather than assuming either is faster by default.
- Debugging tooling is less mature for MCP. REST has decades of debugging tools (curl, Postman, browser devtools). MCP debugging is improving but still has fewer battle-tested options.
Media & source verification
Real published numbers exist, and they’re worth knowing — but they also prove the point above about implementation mattering as much as the protocol. TrueFoundry’s benchmarks put Streamable HTTP (MCP’s current standard remote transport) at roughly 10ms latency per call even under load, sustaining 290-300 requests per second at 100% success in a shared-session deployment. The older SSE-based transport, by comparison, collapsed to 7-30 RPS under the same sustained load with latency climbing into the hundreds of milliseconds — part of why Streamable HTTP replaced it as the spec’s current standard.
But implementation-specific bugs can dwarf any of that: one detailed 2026 benchmark traced an anomalous ~40ms fixed overhead on every HTTP-calling tool back to a specific Rust MCP library (rmcp v0.16) hardcoding SSE-style response framing even for simple stateless replies that should’ve returned plain JSON — inflating latency roughly 35x over the same tool’s actual I/O time. That bug was fixed in v0.17.0. The lesson generalizes directly: a slow MCP server might be measuring the protocol, or it might just be measuring one library’s bug, and you can’t tell the difference without benchmarking your own actual setup.
If you want real numbers for your own server, mcpbench is a purpose-built open-source load tester for exactly this — it speaks JSON-RPC 2.0 over both stdio and HTTP/SSE, tracks per-tool p50/p95/p99 latency distributions, and outputs CI-gateable comparisons, which generic HTTP benchmarking tools can’t do since they don’t understand MCP’s tools/call semantics.
Official reference: the Model Context Protocol specification (modelcontextprotocol.io), TrueFoundry’s stdio-vs-Streamable-HTTP benchmark writeup, and TM Dev Lab’s MCP server performance benchmark, all current as of this writing — transport performance in this space is still shifting quickly enough that specific numbers are worth re-checking against the latest spec revision before citing them elsewhere.
Practical takeaway
Default to REST for anything stable, high-traffic, and consumed by more than just an agent. Reach for MCP specifically at the tool-calling boundary where an agent needs to discover and use capabilities dynamically — not as a wholesale replacement for your existing API layer. If you’re starting a new agentic project today, the pragmatic move is usually: keep your core services on REST, and build the agent-facing tool layer on MCP.
Frequently asked questions
- When does MCP beat a REST API for an AI agent tool layer?
- MCP wins where available actions genuinely change, such as plugins, user-installed extensions, or an evolving toolset, because list_tools tells the model at runtime what it can do. It also gives LLM-native schemas and native stateful sessions, which REST covers with a spec translation layer and custom session code.
- What are the practical drawbacks of MCP over REST today?
- MCP's security model is younger and less battle-tested, quality varies between server implementations, and debugging tooling has fewer battle-tested options than curl, Postman, and browser devtools. Hosting patterns are also still stabilizing while REST has two decades of auth, caching, rate-limiting, and monitoring infrastructure.
- How do I add MCP tool calling to an API I already have?
- Build a thin MCP server that wraps your existing REST endpoints, translating list_tools and call_tool into calls against the API you already have. You get discovery and LLM-native schemas at the agent boundary without duplicating business logic or auth, and your web and mobile consumers stay unaffected.